News and Social Media Monitoring: Sources, Filtering and Digests
Monitoring news and social media comes down to three steps: search the places your audience talks, throw out the posts that only match your keyword by accident, and turn what is left into something a person can read in five minutes.
This guide maps the first step to the sources we cover, each with its own step-by-step guide. Then it walks through all three with a real example: a month of mentions of one brand from Threads, Reddit and Google News, filtered and summarized by Claude, with the numbers and costs from our run.
Every scraper linked here is one of our Actors on Apify. An Actor is a scraper that runs in Apify's cloud: you give it input such as a keyword or a profile, and it returns a dataset you can export as CSV, JSON or Excel. You pay per result, and each guide lists the current price.
Find the guide for your source
| You want to follow | Start with |
|---|---|
| Conversations about a keyword or account on Threads | Threads posts and profiles |
| Financial and business headlines by topic | Bloomberg headlines |
| Crypto news and how readers react to it | CryptoPanic news and votes |
| Chinese social media and trending topics | Weibo posts, comments and hot search |
| What is said inside videos, not just their captions | TikTok video transcripts |
| Creators and their activity | Snapchat profiles and Spotlight |
More sources
Video transcripts: X video posts, Facebook videos and Reels, LinkedIn videos
Actors without a written guide yet: Google News, Reddit, Bing News, Bluesky, Telegram channels
Why keyword results need a second pass
A keyword search returns everything that contains the word, which is not the same as everything about you. Here are six results from our example search for "Supabase", a developer platform, with the call Claude made on each:
| Source | What it said | Call |
|---|---|---|
| TechCrunch | Some Supabase customers are publicly exposing large amounts of personal data | Relevant, negative |
| r/Supabase | A free-tier support ticket took over two months to get an answer | Relevant, mixed, worth a reply |
| Threads | A developer connected Supabase as shared memory for Claude, written in Ukrainian | Relevant, positive |
| r/ForHireFreelance | A Flutter freelancer lists Supabase among their skills | Not relevant |
| r/StartUpIndia | A job ad lists Supabase in the company's stack | Not relevant |
| A resume roast request that never mentions Supabase | Not relevant |
Reddit search matches words anywhere in a post, including long bodies, so it brings the most noise: 21 of its 40 results were not about the brand. The 25 news articles that fell in the period were all relevant. Social posts were somewhere in between.
Example: a month of mentions, filtered and summarized
Our open-source brand mention monitor runs the whole process on your machine, with Postgres in Docker. For the example we tracked "Supabase" over the 30 days to October 7, 2026.
- Search. The Threads Posts Scraper, Reddit Posts Scraper and Google News Scraper ran in parallel and returned 89 results. Posts older than 30 days were dropped, which left 74 mentions: 40 from Reddit, 25 news articles and 9 Threads posts.
- Filter and classify. Claude read every mention against a short description of the brand, including what does not count, such as job ads and skill lists. It kept 51 and gave each a sentiment, a topic, a one-sentence summary and a reply flag.
- Summarize. One more request turned the 51 into a digest: what happened this month, the main themes and the five posts most worth answering, each with what to say.
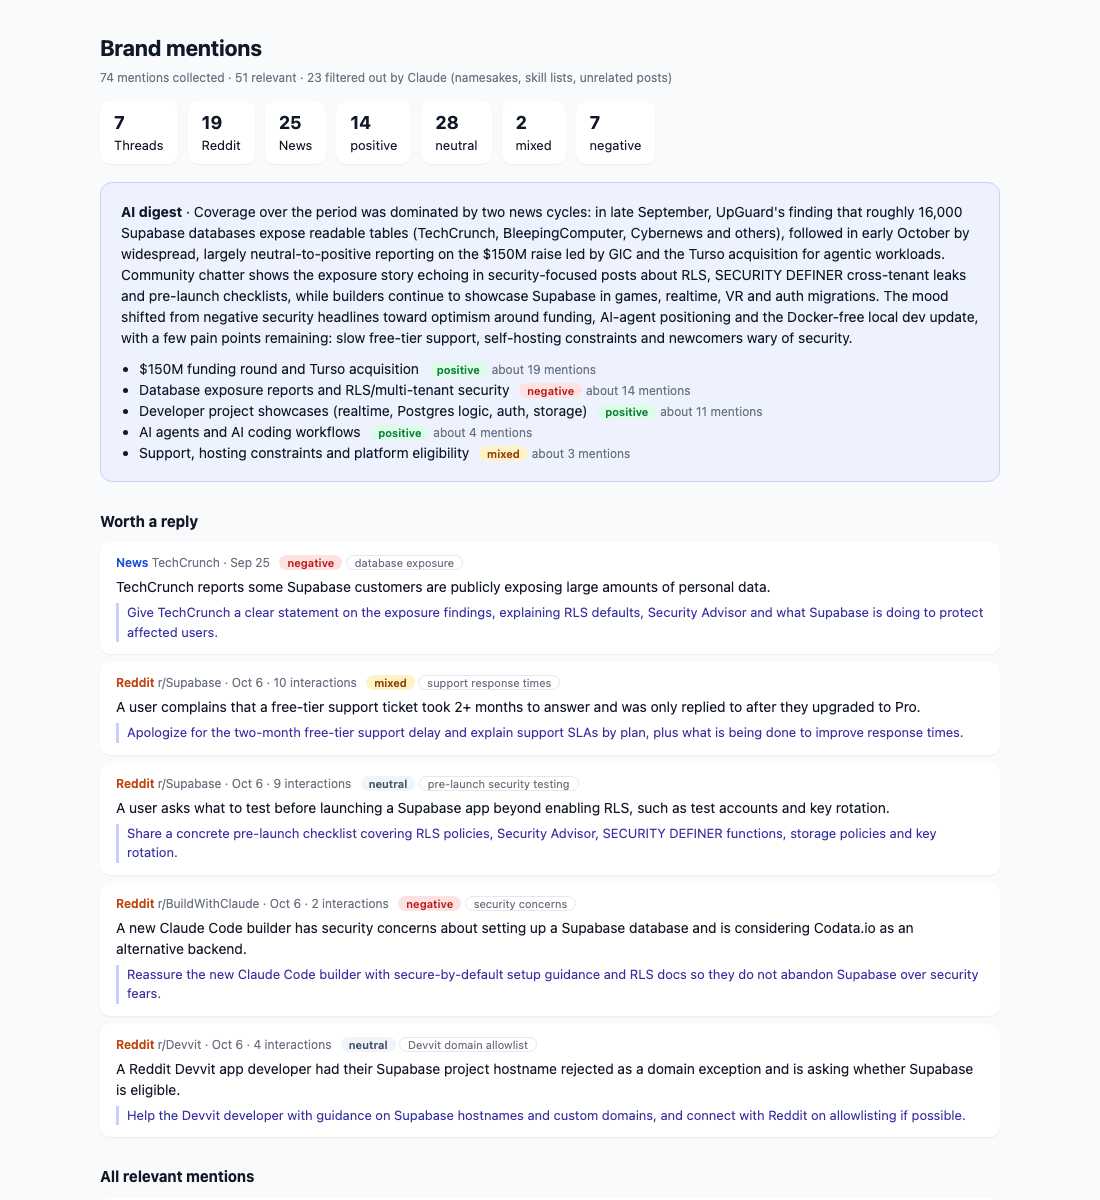
The digest found the two stories of the month without being told about them: a security study about exposed databases in late September, then a funding round and acquisition in early October.
| Theme | Sentiment | Mentions |
|---|---|---|
| $150M funding round and Turso acquisition | Positive | 19 |
| Database exposure reports and multi-tenant security | Negative | 14 |
| Developer project showcases | Positive | 11 |
| AI agents and AI coding workflows | Positive | 4 |
| Support, hosting constraints and platform eligibility | Mixed | 3 |
Its reply list started with the TechCrunch article, suggesting a clear statement on the exposure findings, followed by the support complaint and a developer asking what to test before launching.
Pricing as of October 7, 2026: the three Actors cost $0.0035 per Threads post, $0.002 per Reddit post and $0.0025 per news article, about $0.21 for this run. Claude's classification of the 74 mentions cost $0.35, and later runs only send mentions they haven't seen.
How often to run it
How fresh your data can be depends on what each source returns, so set the schedule per source:
- Reddit and news: daily. Reddit search sorted by newest returns recent posts, and our Actors'
postedAfterinput skips anything older than your last run. Google News returns articles of mixed ages, so filter by publication date as our monitor does. - Threads: daily is plenty. Without an account, Threads shows only the top posts for a keyword, roughly 30, rather than every new one. A daily run catches the posts that gained traction, not all of them.
- Financial headlines: several times a day. Category pages on news sites change through the day. The Bloomberg guide covers tracking new stories between runs.
Running it without code
Any of these Actors can run on a schedule from the Apify Console, and each run's dataset can go to Google Sheets, Slack or a webhook through Apify's integrations. That covers collection and alerts; for the filtering and digest steps, the monitor above adds the AI layer on top.
Posts and articles belong to their authors and publishers. Store what you need for monitoring, link back to the source, and don't republish full articles.
Want this data without writing code?
Every scraper on this site runs on Apify with free starter credits.
Related guides
- Web Scraping in 2026: start here if you're new to scraping
- How to Scrape Without Getting Blocked: proxies, fingerprints and rate limits
- Ecommerce Data Scraping: prices, suppliers and resale values
- Lead Generation with Web Scraping: turn directories into qualified B2B leads